Entity and Relationship Extraction
To process large documents, LLM automatically splits the text into
chunks . Overlapping helps maintain context at boundary sentences.
Each chunk is then sent to the LLM with a prompt instructing it to
extract SPO triples. Hao Wu developed a tool to extract
entity and relationship out of a small text (Hao Wu,
2025). The ai-knowledge-graph utility will use the configured LLM of
your choice to extract knowledge from the above text and create an
knowledge graph html as output. See for the example text, the
article. For each chunk, the tool asks the LLM to output a JSON array
of triples and what chunk the information what extracted from.
JSON
(JavaScript Object Notation) is an open standard file format and
data interchange format that uses human-readable text to store and
transmit data objects consisting of name–value pairs and arrays (or
other serializable values). It is a commonly used data format with
diverse uses in electronic data interchange, including that of web
applications with servers.
The standard is described in RFC 8259 STD 90.
We do not use the tool of Hao Wu, but perform the same steps manually,
because that tool is too demanding in terms of hardware.
See PuppyGraph.
Example below how to use the prompt:
Return only structured JSON, with no explanation in the form (entity_1, relationship, entity_2) of the following text:
Feedback is a concept from cybernetics. It was introduced and was the subject of heated debate during the Cybernetica conferences of the Macy Group between 1946 and 1953.
These were some of the first structured studies into interdisciplinarity. They formulated new concepts in the fields of systems theory, cybernetics and what would later become known as cognitive science.
See the result:
[
  {
    "entity_1": "Feedback",
    "relationship": "is a concept from",
    "entity_2": "cybernetics"
  },
  {
    "entity_1": "Feedback",
    "relationship": "was the subject of heated debate during",
    "entity_2": "the Cybernetica conferences of the Macy Group"
  },
  {
    "entity_1": "the Cybernetica conferences of the Macy Group",
    "relationship": "took place between",
    "entity_2": "1946 and 1953"
  },
  {
    "entity_1": "the Cybernetica conferences of the Macy Group",
    "relationship": "were some of the first structured studies into",
    "entity_2": "interdisciplinarity"
  },
  {
    "entity_1": "the Cybernetica conferences of the Macy Group",
    "relationship": "formulated new concepts in",
    "entity_2": "systems theory"
  },
  {
    "entity_1": "the Cybernetica conferences of the Macy Group",
    "relationship": "formulated new concepts in",
    "entity_2": "cybernetica"
  },
  {
    "entity_1": "the Cybernetica conferences of the Macy Group",
    "relationship": "formulated new concepts in",
    "entity_2": "cognitive science"
  }
]
Google AI was used for this. Other LLMs may produce different results.
JSON databases can be queried using JSON Query.
The example above can easily be converted into the process notation used by Edugraph. If you are not yet acquainted to the grammar of the process notation, Edugraph can also convert it automatically.
name:experiment_triplets
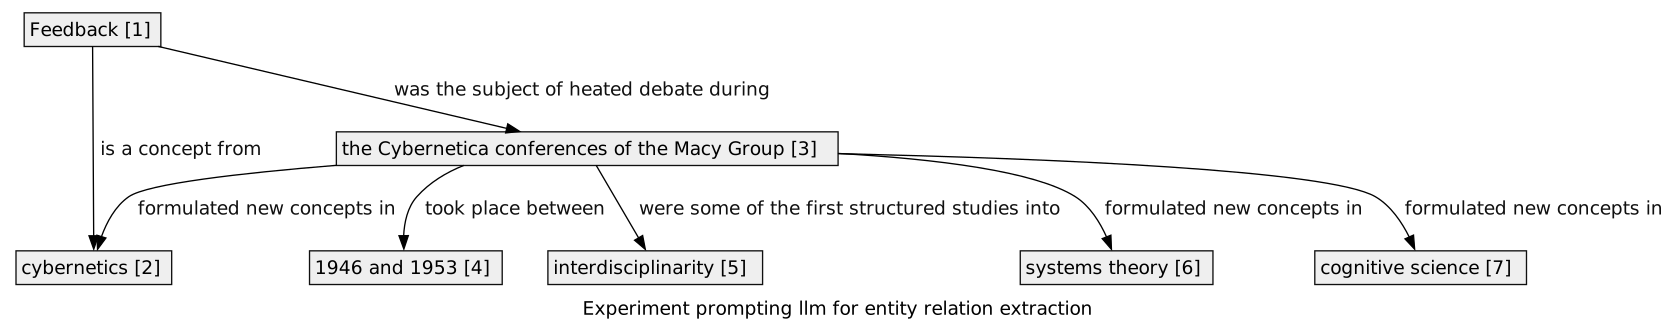
is a concept from [1,2] = Feedback [1] » cybernetics [2],
was the subject of heated debate during [1,3] = Feedback [1] » the Cybernetica conferences of the Macy Group [3],
took place between [3,4] = the Cybernetica conferences of the Macy Group [3] » 1946 and 1953 [4],
were some of the first structured studies into [3,5] = the Cybernetica conferences of the Macy Group [3] » interdisciplinarity [5],
formulated new concepts in [3,6] = the Cybernetica conferences of the Macy Group [3] » systems theory [6],
formulated new concepts in [3,2] = the Cybernetica conferences of the Macy Group [3] » cybernetics [2],
formulated new concepts in [3,7] = the Cybernetica conferences of the Macy Group [3] » cognitive science [7],
label:Experiment prompting llm for entity relation extraction.
It results in the following graph:
Also causal relations vusing the LLM prompt
This prompt also works:Return only structured JSON, with no explanation in the form (entity_1, causal relationship, entity_2) of the following text:
The result:
[
  {
    "entity_1": "Cybernetica conferences of the Macy Group",
    "causal_relationship": "introduced and debated",
    "entity_2": "Feedback"
  },
  {
    "entity_1": "Cybernetica conferences of the Macy Group",
    "causal_relationship": "were some of the first structured studies into",
    "entity_2": "interdisciplinarity"
  },
  {
    "entity_1": "Cybernetica conferences of the Macy Group",
    "causal_relationship": "formulated new concepts in",
    "entity_2": "systems theory"
  },
  {
    "entity_1": "Cybernetica conferences of the Macy Group",
    "causal_relationship": "formulated new concepts in",
    "entity_2": "cybernetics"
  },
  {
    "entity_1": "Cybernetica conferences of the Macy Group",
    "causal_relationship": "formulated new concepts in",
    "entity_2": "cognitive science"
  }
]
Although it might be more accurate to speak of ‘an influence on’ in this context. This answer is unlikely to pass the counterfactual test.
post-processing
PEven a thorough reading of the text may not capture implied relationships. This can be addressed in two ways:
Rule-Based Inference:
Transitive Relationships: If A enables B, and B drives C, the system can infer A influences C.
Lexical Similarity: Entities with similar names might be linked with a generic “related to” relationship.
LLM-Assisted Inference:
One can prompt the LLM to propose links between otherwise disconnected subgraphs. For example, if one cluster is about the Industrial Revolution and another is about AI, the LLM might infer a historical or conceptual connection (“AI is an outgrowth of technological innovation that began in the Industrial Revolution”).
These edges are marked differently (e.g., dashed lines) to distinguish them from explicitly stated facts.
This inference step often adds a large number of new relationships, greatly reducing isolated sub-networks.